Key takeaways
- Multi-cloud environments usually accumulate rather than being designed, through team preferences, GPU and AI service availability, acquisitions, and data sovereignty requirements. Flexera's State of the Cloud surveys have consistently found that close to nine in ten organizations report a multi-cloud strategy.
- The four core challenges of multi-cloud management are operational fragmentation, security and compliance gaps, cost overruns, and limited visibility. They compound one another, so fixing only one rarely delivers much improvement.
- Unified multi-cloud management is more valuable as a single point of action than as a single pane of glass. One control plane should let teams apply a policy, roll out a cluster upgrade, or grant access once and have the change propagate to every environment.
- Effective multi-cloud infrastructure management rests on four pillars: automation and orchestration to centralize control, Infrastructure as Code for consistency, centralized security and governance, and FinOps for cost visibility, allocation, and waste reduction across providers.
- Kubernetes is the practical common layer for multi-cloud deployments. When every environment exposes a conformant Kubernetes API with the same add-ons and policies, teams can use one provider-agnostic CI/CD pipeline and deploy the same manifests everywhere instead of maintaining separate pipelines for each cloud.
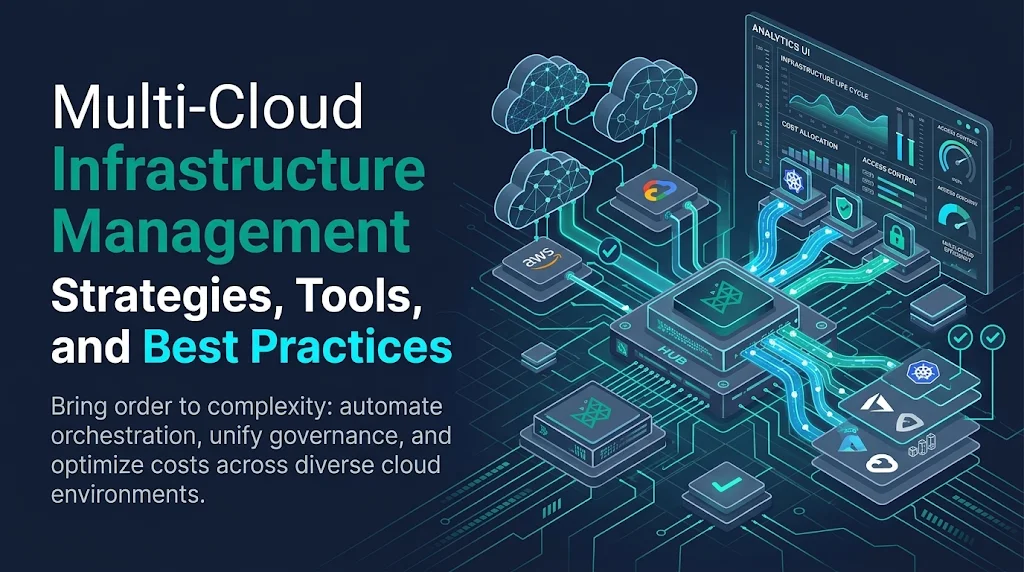
Managing infrastructure across multiple cloud providers offers flexibility, but differences in provisioning, security, and billing can make operations complex. Multi-cloud infrastructure management helps organizations coordinate these environments through consistent automation, governance, and cost controls.
This guide covers the main challenges, four key management pillars, and the tools and practices that help organizations manage multi-cloud infrastructure effectively.
Why Multi-Cloud Infrastructure Becomes Difficult to Manage
Nobody sets out to build a fragmented estate. It accumulates. One team standardizes on AWS because the data warehouse lives there. The ML group moves training to GCP for TPU access and Vertex AI. An acquisition brings in an Azure tenant tied to a Microsoft enterprise agreement. Meanwhile, regulated workloads stay on-premises for data sovereignty reasons, which makes you hybrid cloud whether or not anyone planned it.
The data confirms how common this is. Flexera's annual State of the Cloud surveys have consistently found that close to nine in ten organizations report a multi-cloud strategy. Multi-cloud adoption is the default operating condition for large enterprises, and the drivers are sound:
- Avoiding vendor lock-in. Negotiating use disappears when every workload depends on one provider's proprietary services.
- Best-of-breed services. GPU availability, managed AI services, and pricing differ across AWS, Azure, and GCP. During GPU shortages, the ability to place training jobs wherever capacity exists becomes a scheduling advantage.
- Resilience. Regional outages happen. Spreading critical services across providers limits the blast radius.
The problem is that these benefits are realized at the workload level while the costs land at the platform level. Each cloud adds its own identity model, networking constructs, Kubernetes distribution, and billing format. Without a deliberate management strategy, you inherit every provider's complexity and gain none of the use.
The Core Challenges of Multi-Cloud Management
We see the same four problems in almost every organization we work with. They compound each other, which is why fixing just one rarely helps much.
Operational Fragmentation
EKS, AKS, and GKE are all Kubernetes, but upgrading, networking, and autoscaling them are three different jobs. Teams end up building provider-specific runbooks, provider-specific pipelines, and provider-specific expertise. The platform team becomes three platform teams sharing a Slack channel. Data scientists wait days for a GPU environment because the request has to route through whichever group owns that cloud.
Security and Compliance Gaps
AWS IAM, Azure Entra ID with RBAC, and GCP IAM express permissions differently. Translating one policy intent ("ML engineers can deploy to staging but not production") into three native implementations invites drift. Auditors ask for evidence that controls are applied uniformly, and most teams can only produce screenshots from three consoles. For AI workloads touching sensitive training data, that gap is a sovereignty and auditability problem, not just a hygiene issue.
Cost Overruns
Cloud spend becomes unpredictable when nobody can see it in one place. GPU instances make this worse: an idle A100 or H100 node left running over a weekend costs more than many CPU clusters do in a month. Flexera respondents regularly estimate that more than a quarter of their cloud spend is wasted, and in our experience GPU fleets without scheduling discipline run worse than that.
Limited Visibility
You cannot fix what you cannot see. When monitoring, logging, and inventory live in provider-native tools, answering basic questions ("How many clusters are running Kubernetes versions past end of support?") requires manual correlation. Incident response slows down because the first hour goes to figuring out where the problem lives.
The Strategic Benefits of a Unified Management Approach
Unified management means one control plane defines how infrastructure is provisioned, secured, deployed, and paid for, regardless of where it runs. The provider-specific details still exist; they are handled once, in code and policy, instead of repeatedly by people.
The "single pane of glass" phrase gets overused, and vendors often mean a dashboard that aggregates metrics. That is the least valuable part. What matters is a single point of action: one place to apply a policy, roll out a cluster upgrade, or grant a team access, with the change propagating to every environment.
When that exists, several outcomes follow:
- Faster incident resolution. Engineers query one inventory and one set of logs instead of three.
- Stronger security posture. A policy defined once applies everywhere, so there is no window where one cloud lags behind.
- Cost control. Spend and resource utilization are attributed to teams and projects consistently across providers.
- Self-service with guardrails. Developers and data scientists request environments from a catalog of approved templates, and governance is built into the template rather than enforced by ticket review.
That last point is where most organizations see the biggest change in delivery speed. The bottleneck in AI development is rarely the model code. It is waiting for infrastructure.
Four Pillars of Effective Multi-Cloud Infrastructure Management
A consistent multi-cloud strategy requires more than managing each provider separately. These four pillars help organizations coordinate infrastructure provisioning, configuration, security, and cost management across environments.
Pillar 1: Centralizing Control with Automation and Orchestration
Consider a data science team that needs a GPU-enabled Kubernetes cluster with specific drivers, monitoring, and network isolation. Manual provisioning can involve several teams and handoffs. Automation can reduce this effort by applying predefined configurations consistently.
Automation typically covers three areas:
- Resource provisioning: Create clusters, node pools, storage, and networking from templates.
- Configuration management: Apply add-ons, drivers, operators, and baseline settings consistently.
- Policy enforcement: Apply admission controls, quotas, and network policies during provisioning.
Orchestration coordinates these tasks across systems and providers. For example, a workflow might provision a cluster on GCP, register it with an identity provider, deploy a GPU operator, apply tenant quotas, and notify the requesting team. It can also handle failures through retries or rollback where supported.
Automation should cover exceptions as well as routine tasks. Driver compatibility, certificate rotation, and cross-cloud networking can introduce configuration drift if they remain manual. Building reliable automation takes upfront investment in templates and testing, but can make it easier to add regions or providers.
Pillar 2: Maintaining Consistency with Infrastructure as Code (IaC)
Infrastructure as Code defines infrastructure in version-controlled files, making changes easier to review, reproduce, and audit.
Terraform is widely used for multi-cloud IaC because it supports multiple providers through a common workflow. However, a shared syntax does not make cloud resources identical. AWS EKS and Azure AKS, for example, still have provider-specific configurations. Reusable modules can provide a consistent interface while handling those differences behind the scenes.
IaC supports multi-cloud management in several ways:
- Standardization: Encode security baselines, logging, and tagging in reusable modules.
- Repeatability: Recreate environments through automated workflows.
- Version control: Track changes and revert configuration when needed.
- Reviewability: Allow security and FinOps teams to review infrastructure changes before deployment.
IaC also has limitations. Teams need to manage state, prevent configuration drift caused by manual changes, and account for Kubernetes resources that change more frequently than the underlying infrastructure. Using IaC for provisioning alongside GitOps-style reconciliation for cluster configuration and workloads can help address these challenges.
Pillar 3: Strengthening Multi-Cloud Security and Governance
Security policies need to be applied consistently across cloud providers, clusters, and workloads. A multi-cloud strategy should cover infrastructure configuration, policy enforcement, identity management, and compliance monitoring.
Define Security in Code
Set encryption, private endpoints, network segmentation, and logging requirements in IaC modules so they are applied consistently during provisioning.
Centralize Policy Enforcement
Tools such as Open Policy Agent and Kyverno can help enforce Kubernetes policies across environments. Rules might prevent containers from running as root, restrict public load balancers, or limit GPU workloads to approved images.
Unify Identity and Access
Use federated identity where appropriate, map permissions to roles and groups, and apply least-privilege access. Cloud IAM and Kubernetes RBAC must both be considered to avoid gaps between infrastructure-level and cluster-level permissions.
Build Compliance Into Delivery Pipelines
Integrate infrastructure scanning, image vulnerability checks, and policy tests into CI/CD pipelines. Continuous monitoring can help teams identify violations and collect evidence for audits across environments.
Multi-tenant AI platforms also need clear isolation between tenants. Network policies, resource quotas, separate credentials, and audit trails help control access and track resource consumption. These records can support both governance and cost allocation.
Pillar 4: Controlling Costs with Multi-Cloud FinOps
FinOps brings engineering and finance together to understand and manage cloud spending. Across multiple providers and on-premises infrastructure, a consistent view of costs helps teams identify waste and make informed resource decisions.
Unified Cost Visibility
Normalize billing and usage data from different providers into a shared view. This helps teams compare spending and utilization across environments.
Cost Allocation Through Tagging and Labeling
Apply tags for team, project, and environment during provisioning. At the Kubernetes level, allocate shared cluster costs to namespaces and workloads where possible, so teams can understand their contribution to overall spend.
Rightsizing Resources
Compare requested resources with actual usage and adjust allocations. Some workloads may need less CPU or GPU capacity than initially assigned, while others may require more.
Eliminating Idle Resources
Schedule non-production environments to shut down when they are not needed. Time-to-live policies for experimental clusters and rules for reclaiming idle GPU resources can also reduce unnecessary spending.
Managing Cloud Commitments
Reserved instances and savings plans can reduce costs when usage is sufficiently predictable. Review consumption patterns before committing to long-term capacity.
Understanding GPU Economics
For enterprises, better GPU utilization helps make more effective use of existing or reserved capacity. For cloud service providers and neoclouds, accurate per-tenant usage tracking is also important for billing customers for compute consumption.
Cost management is not only a tooling issue. Teams need to consider cost alongside performance and reliability when designing and operating workloads. Usage reports and cost data integrated into engineering dashboards can help make spending more visible and actionable.
The Role of Cloud Management Platforms (CMPs) in Unification
The four pillars describe what needs to happen. A Cloud Management Platform is the tooling that makes them operate as one system. A CMP provides centralized control, automation, and visibility across providers, abstracting the differences so your teams work against one interface.
Core functionality to evaluate:
- Unified visibility into resources, deployments, health, and spend across every cloud and data center.
- Provisioning and lifecycle automation, including upgrades, which is where most homegrown tooling falls apart.
- Centralized policy and access management that applies consistently everywhere.
- Cost management with allocation down to the team and workload.
- Self-service catalogs that let developers consume approved infrastructure without filing tickets.
Not all multi-cloud tools address the same problem. Some are cost-only tools. Some are monitoring aggregators. Some are VM-era CMPs that treat Kubernetes as an afterthought. For organizations running cloud-native and AI workloads, the CMP needs to understand Kubernetes and GPUs natively, because that is where the operational complexity now lives.
A build-versus-buy note: many platform teams start by assembling open-source components (Terraform, Argo CD, OPA, Prometheus, a cost tool) into an internal platform. This works, and we respect teams that do it well. The cost shows up in year two, when the team spends most of its time maintaining the integration between components instead of serving developers. Be honest about whether platform plumbing is where you want your best engineers spending their time.
Extending DevOps Principles Across Your Cloud Environments
DevOps practices were designed to close the gap between building software and running it. Multi-cloud reopens that gap, because the "ops" side now spans environments with different behaviors. Extending DevOps means designing pipelines and team practices that don't care which cloud is the target.
In practice:
1. Build provider-agnostic CI/CD pipelines. The pipeline should build an artifact once, test it once, and deploy it to any registered environment through the same stages. Environment-specific details (credentials, endpoints, cluster targets) come from configuration, not from separate pipelines per cloud. If you maintain one pipeline for AWS and another for Azure, you are maintaining two sets of bugs.
2. Treat IaC as part of the delivery pipeline. Infrastructure changes go through the same review, testing, and promotion as application code. This is where IaC stops being a platform team concern and becomes a shared practice.
3. Standardize the deployment target. Kubernetes is the practical common layer. When every environment exposes a conformant Kubernetes API with the same add-ons and policies, application teams deploy the same manifests everywhere.
4. Extend DevOps to MLOps. AI workloads add model training, evaluation, and serving to the pipeline. Training may run on whichever cloud has GPU capacity this week, while inference runs close to users or data. The pipeline needs to handle placement decisions without data scientists having to understand the underlying infrastructure.
5. Share ownership of reliability. SRE practices, service-level objectives, and blameless postmortems apply across clouds. Unified observability makes this possible; without it, every incident starts with an argument about whose dashboard is correct.
The Collaboration Piece Matters as Much as the Tooling
Platform teams that treat developers as customers, publish golden paths, and measure time-to-first-deployment build platforms people use. Platform teams that mandate tools without solving real friction build platforms people route around.
Orchestrating Your Multi-Cloud Strategy with Rafay
Rafay’s Infrastructure Orchestration & Workflow Automation Platform helps enterprises and cloud service providers manage multi-cloud infrastructure without relying on disconnected scripts, tickets, and consoles.
Here’s how Rafay addresses common challenges:
- Fragmentation → Unified Kubernetes management. Manage Kubernetes clusters across public clouds, private data centers, and edge locations through one control plane, with consistent workflows for provisioning, upgrades, and configuration.
- Slow delivery → Governed self-service. Give developers and data scientists on-demand access to compute through curated templates, with security settings, quotas, and cost controls defined by platform teams.
- Security and compliance gaps → Centralized policy and access. Define policies and access controls centrally and enforce them across managed environments, with audit trails to support compliance and data sovereignty requirements.
- Cost overruns → GPU and CPU resource visibility. Track infrastructure consumption to support cost allocation, reduce waste, and inform capacity planning.
- Multi-tenant AI platforms → AI Factory approach. Help enterprises, cloud service providers, and neoclouds offer shared GPU infrastructure to different teams or customers with appropriate tenancy controls and guardrails.
Rafay works alongside tools teams already use, including Terraform, GitOps workflows, and existing CI/CD pipelines. Rather than treating automation, IaC, security, and FinOps as separate initiatives, the platform brings these practices together through infrastructure orchestration.
If your platform team spends more time maintaining infrastructure than enabling developers and data scientists, start by mapping your provisioning workflow and identifying manual handoffs. This can help reveal where orchestration could simplify operations and improve delivery.
Frequently Asked Questions
What are the common challenges businesses face when managing multiple cloud environments?
Businesses often struggle with operational fragmentation, where different cloud services require unique management approaches. Other challenges include security and compliance gaps due to varied identity models, unpredictable cost overruns, and limited visibility into resources and spending across providers.
How does Infrastructure as Code (IaC) ensure consistency in multi-cloud deployments?
IaC ensures consistency by defining infrastructure in version-controlled files, enabling standardized provisioning, and repeatable deployments across clouds. This approach guarantees that every environment adheres to predefined configurations and security baselines, minimizing drift and facilitating reviews.
What practical strategies help control escalating costs in a multi-cloud environment?
Practical strategies include normalizing billing data for unified visibility, allocating costs accurately using tagging, and rightsizing resources based on actual usage. Eliminating idle resources and strategically managing commitment plans like reserved instances also significantly reduce waste and optimize spend.
How can organizations implement strong and consistent security policies across multiple cloud providers?
Organizations should define security settings proactively in code as defaults, centralize policy enforcement with provider-neutral tools like Open Policy Agent, and unify identity and access management to a single provider. Integrating security checks into CI/CD pipelines ensures continuous compliance across all environments.
Why is multi-cloud orchestration more effective than basic automation for infrastructure management?
Multi-cloud orchestration coordinates complex workflows across disparate systems and providers, handling sequences of tasks like provisioning, configuration, and policy application. While automation executes individual tasks, orchestration ensures successful execution with rollbacks or retries, preventing fragmentation and drift across environments.
What is the most efficient way to manage expensive GPU clusters across different cloud providers?
The most efficient way involves unified management through a single control plane that provisions, monitors, and optimizes GPU resources across clouds. Implementing robust FinOps practices like precise cost allocation, rightsizing, and automated shutdown of idle GPU nodes is crucial for maximizing utilization and controlling expenses.
How do Cloud Management Platforms (CMPs) simplify the complexities of multi-cloud infrastructure?
CMPs simplify multi-cloud infrastructure by offering a single control plane for centralized visibility, automation, and management across diverse providers. They abstract away provider-specific complexities, enabling consistent provisioning, policy enforcement, cost control, and self-service capabilities from one unified interface.