Rafay Token Factory turned an optimized Qwen3.6-27B worker into a governed, multi-tenant, token-metered service, with 99.97% billing-accurate usage records and about 1% serving overhead. The efficiency inside the worker came from Minima, running Qwen3.6-27B on a single Blackwell GPU against a strong FP8 baseline.
The result: 392.2 output tokens per second at the engine. 387.6 through the full Rafay governance layer, with quotas, metering, and multi-tenant controls included. That is 52.6% more throughput than a strong FP8 baseline, with no measurable drop in quality.
GPU capacity does not become valuable the moment a model loads. It becomes valuable once developers can call it reliably, and once an operator can control, measure, price, and reproduce the service built around it. Closing that distance between raw performance and an operable service was the point of this joint experiment. It is really two problems: making inference efficient, and making it governable.
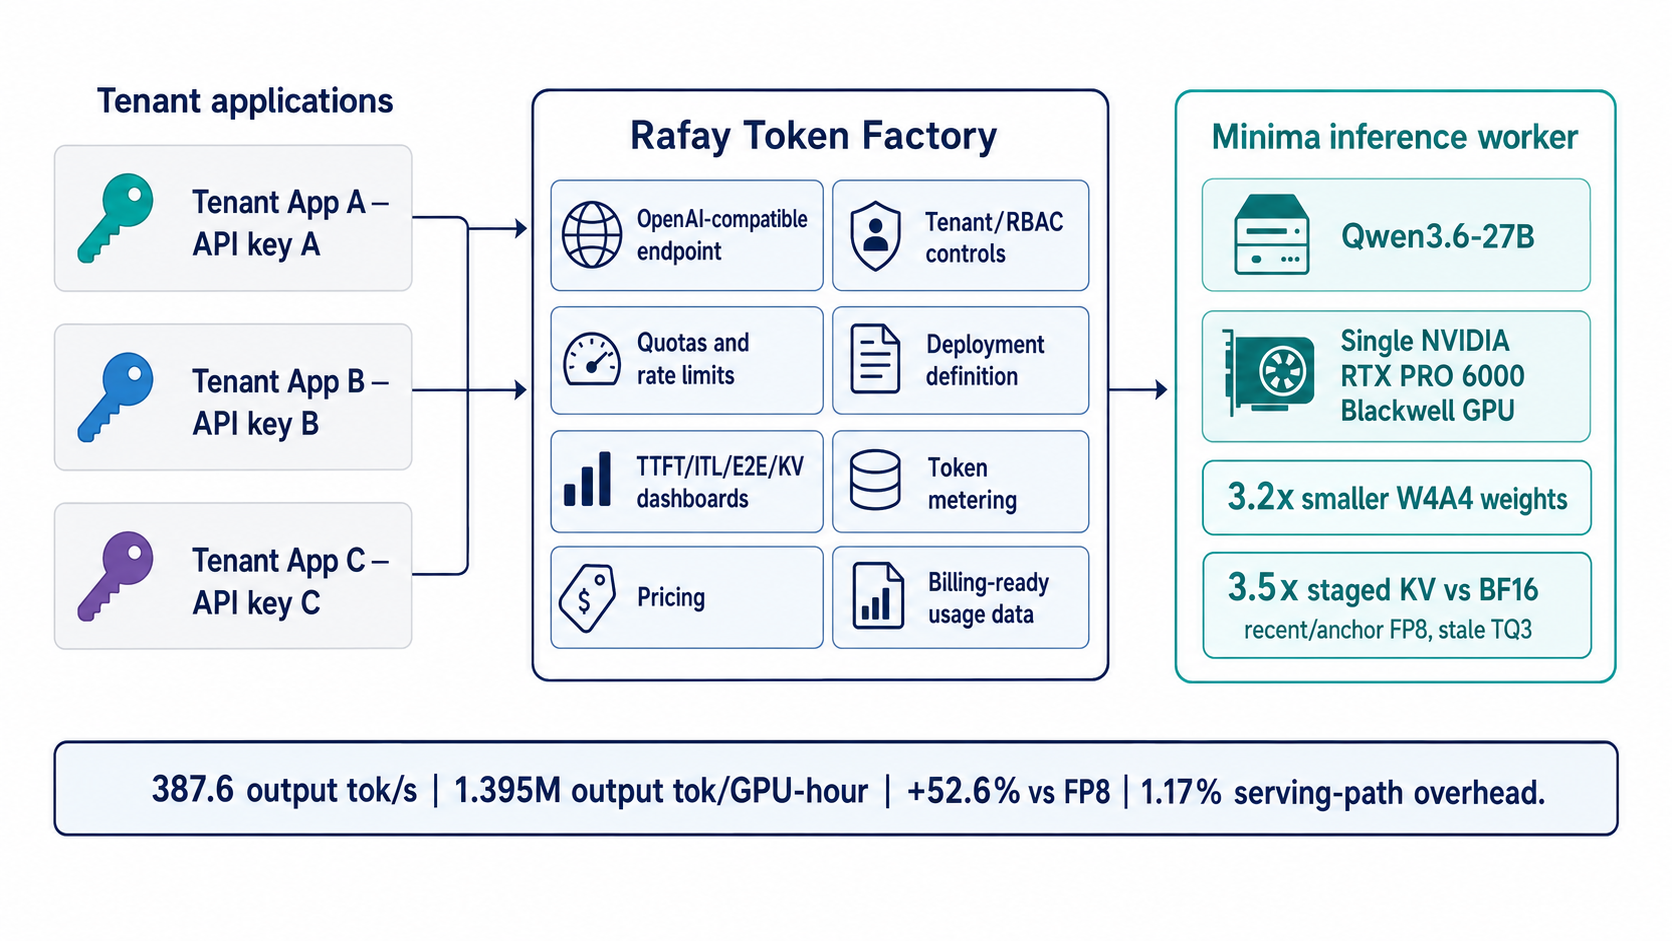
To test both at once, the teams deployed the language-model path of Qwen3.6-27B on a 96 GB NVIDIA RTX PRO 6000 Blackwell Server Edition GPU. Minima took on the first problem, reducing the memory and compute required inside the worker. Rafay Token Factory took on the second, publishing that same worker as an OpenAI-compatible, multi-tenant endpoint with API access, quotas, rate limits, metrics, and token-level usage records.
Token Factory wraps any inference engine, top and bottom. Beneath the engine sits the Rafay platform: GPU scheduling, multi-tenancy, model registry, autoscaling, monitoring, and cluster lifecycle. Above it sits the Rafay control layer: authentication, role-based access, quotas, token metering, rate limiting, and a self-service portal. In this test the engine was Minima's optimized Qwen worker, and it could as readily have been another. The governed service around it stays the same.
Both problems were solved at the same time, in the same stack: a governed inference service an operator could offer to customers or internal teams, running at the full efficiency the hardware can deliver, without building the service layer from scratch.
The test measured the full service
The comparison used the same model revision, prompts, scheduler settings, and GPU. The baseline used FP8 weights, activations, and KV cache with optimized Blackwell kernels. The Minima configuration used Blackwell-native NVFP4 W4A4 execution, Qwen-specific kernels including Gated DeltaNet paths, and a staged attention KV cache that keeps recent and anchor pages in FP8 and stale pages in TurboQuant 3-bit.
For the interactive load point, the test sent 32 requests at concurrency eight, with roughly 512 input tokens and up to 256 output tokens. Each scored point was warmed and repeated five times. The test also ran long-context memory tests, a fixed quality suite, tenant-policy checks, token reconciliation, and a 24-hour mixed-tenant soak.
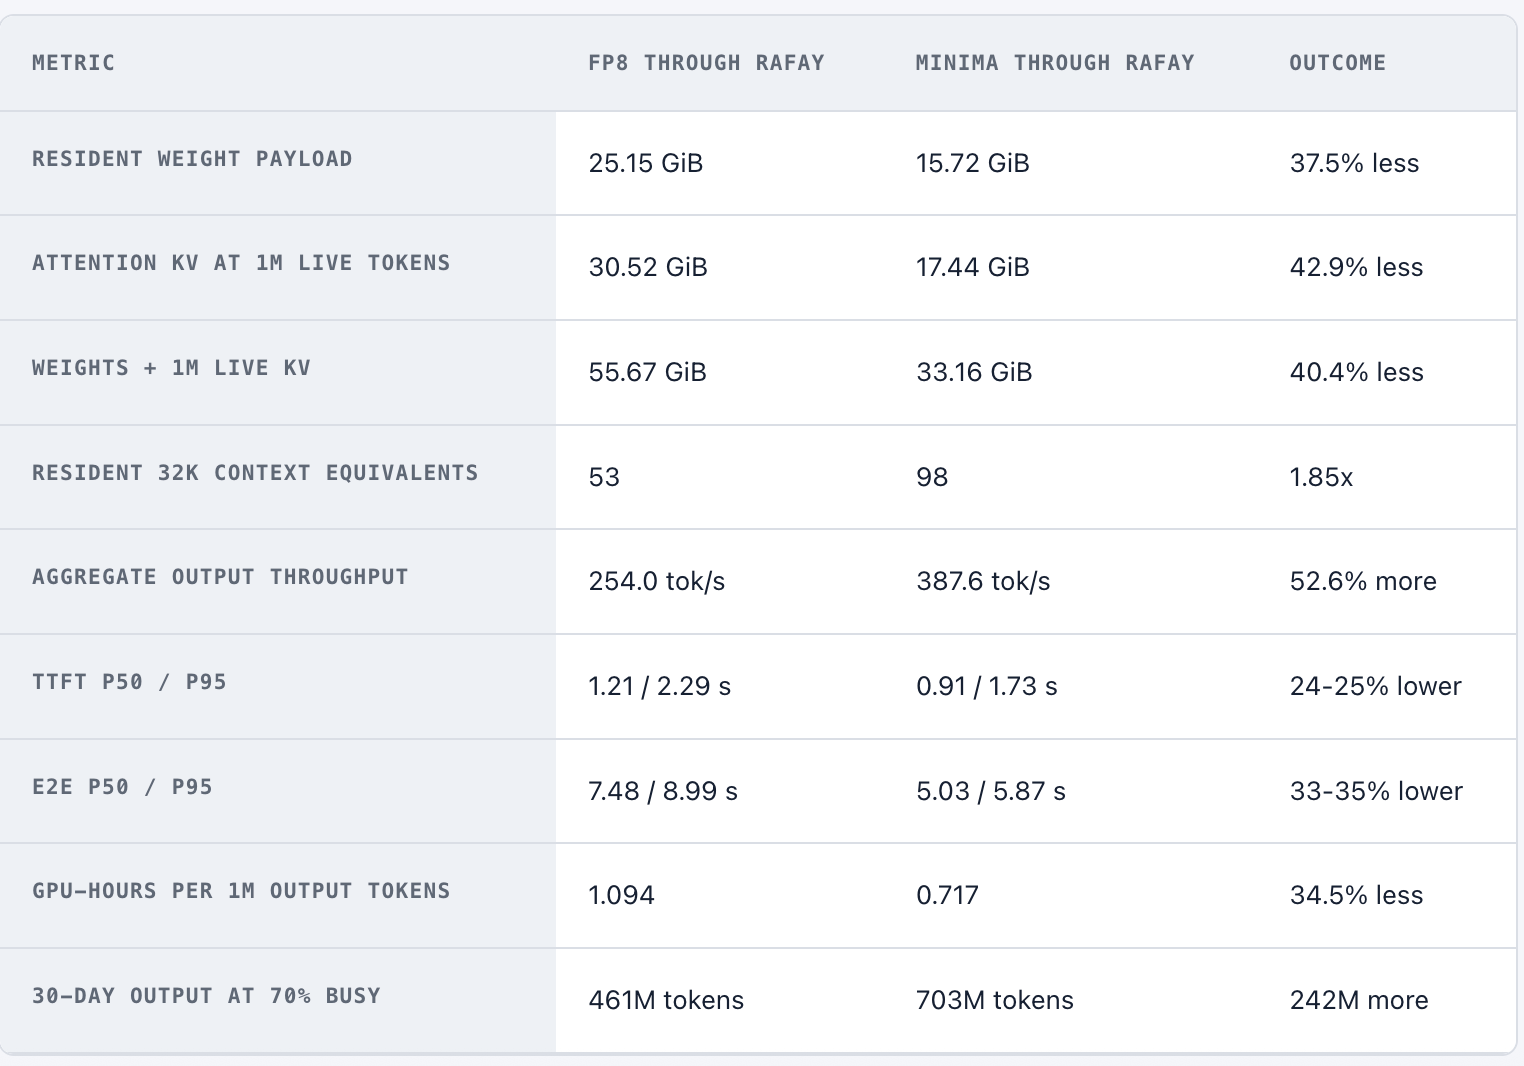
Compression basis. The 3.2x weight and 3.5x attention-KV ratios are both measured against BF16. Against the strong FP8 baseline, Minima used 37.5% less weight memory and 42.9% less attention-KV memory. The ratios apply to different memory pools and are not multiplied.
The result on one Blackwell GPU
Resident-context figures use an 86.4 GiB serving envelope and include the model's fixed DeltaNet sequence state. They are memory ceilings, not a claim that all sequences can decode concurrently at the same SLO.
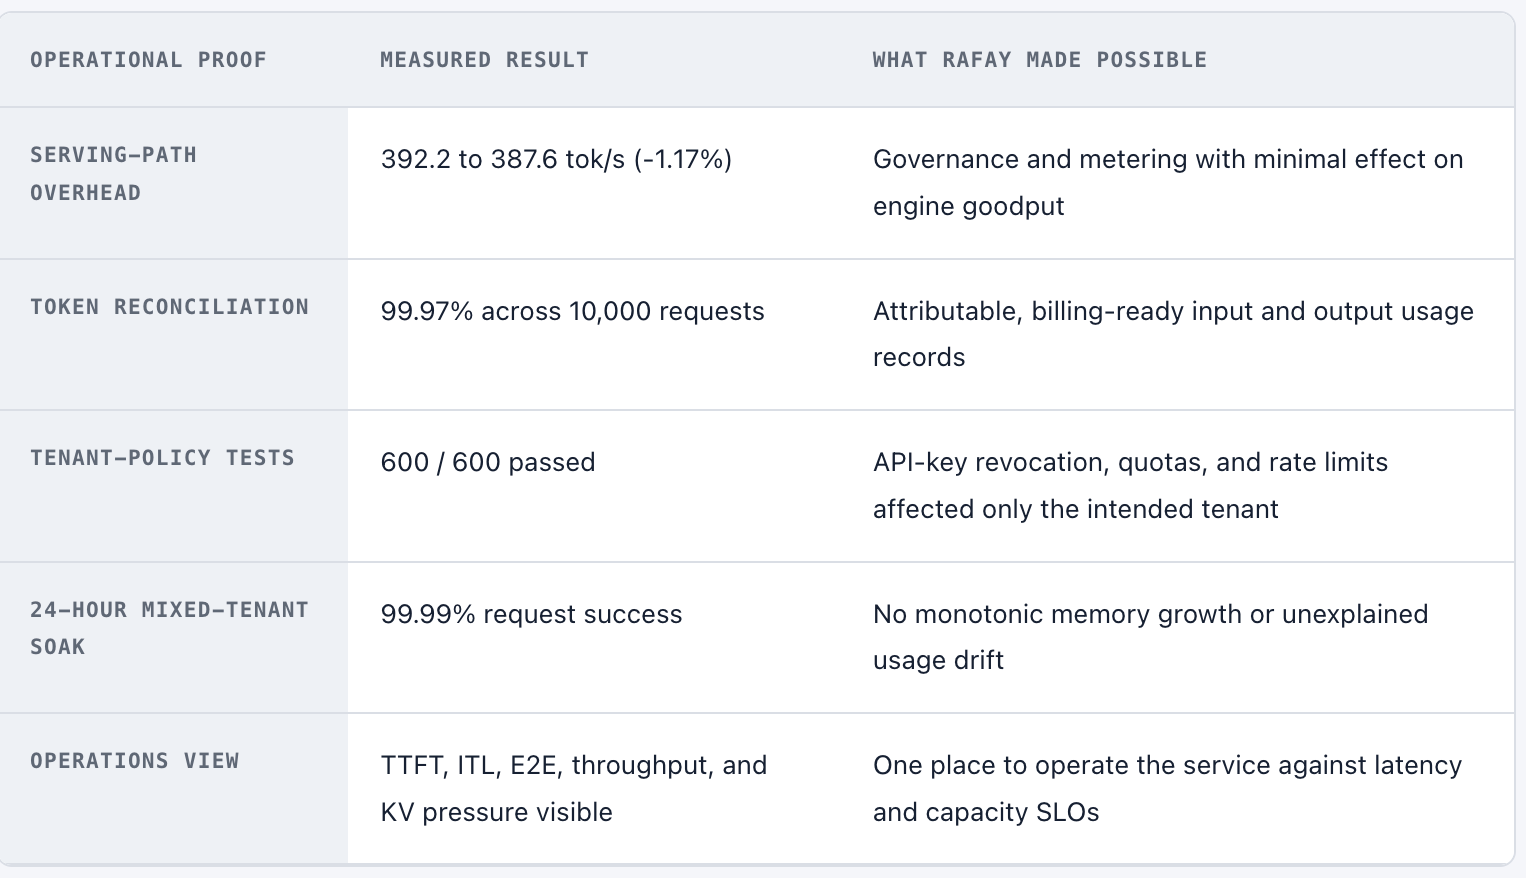
The Minima worker delivered 392.2 aggregate output tokens per second when addressed directly. The same worker delivered 387.6 tokens per second through the Rafay-published endpoint. The matched FP8 service delivered 254.0 tokens per second through the same path. End to end, throughput rose 52.6% and GPU time per million output tokens fell 34.5%.
Quality stayed flat. Across MMLU-Pro, GPQA Diamond, HumanEval+, IFEval, and long-context retrieval, the combined configuration averaged 0.03 percentage points below the BF16 reference, inside the pre-agreed non-inferiority gate of plus or minus 0.5 points. Passkey retrieval matched BF16 at 8K, 32K, 128K, and 262K context.
Rafay closed the gap between benchmark and business
Minima changed the economics inside the worker. Rafay changed what the operator could do with that worker. Token Factory bound the pinned Minima image and Qwen artifact to the Blackwell GPU, published the deployment through an OpenAI-compatible endpoint, and exposed it to three test tenants with separate API keys, quotas, and rate limits.
Developers called the model through the same OpenAI-compatible API using a per-tenant key, with no change to client code. Platform teams tracked TTFT, inter-token latency, end-to-end latency, throughput, and KV-cache pressure in one operations view, and enforced per-tenant quotas and rate limits. Operators received per-request, per-tenant token counts, reconciled at 99.97%, ready to feed pricing, chargeback, showback, or external billing. The same optimized worker ran as a metered service that three isolated tenants used at once. The Rafay platform provided the endpoint, metering, multi-tenancy, and billing-ready data as standard capabilities, so the operator shipped the service without building any of it.
More efficient tokens create more strategic options
At the same hourly GPU cost, the joint service reduced the infrastructure requirement from 1.094 to 0.717 GPU-hours per million output tokens. At 70% sustained load, one GPU moved from about 461 million to about 703 million output tokens per 30-day month. These figures reflect GPU-hours only. Serving cost, power, platform overhead, and support are not included.
Protect margin. Keep the token price stable while reducing the infrastructure cost of each successful output.
Compete on price. Pass part of the efficiency gain to customers while retaining the margin improvement.
Serve more demanding workloads. Use the memory headroom for more tenants, longer contexts, or distinct shared and dedicated service tiers.
Make economics visible. Use Rafay's token attribution and pricing layer to connect production cost with each tenant, business unit, or external customer.
Publishing a Token Factory does not change who the operator is. It expands the operator's addressable base to a second group of buyers, the developers, enterprises, and internal business units that consume tokens rather than rent GPUs.
For a neocloud, telco, or sovereign AI provider, the gain becomes a differentiated, higher-margin model SKU. For an enterprise platform team, it becomes a governed internal service with auditable consumption. In both cases, Rafay turns Minima's performance gain into an operating and economic advantage.
Performance becomes valuable when it becomes operable
Minima made each Blackwell worker produce more useful token capacity. Rafay made that capacity discoverable, governable, observable, measurable, and sellable Together, the two companies moved Qwen3.6-27B from an optimized runtime result to a production-shaped token service: 52.6% more output per GPU than the matched FP8 service, 1.85x the resident 32K context capacity, quality parity, and billing-ready multi-tenant operations. For operators building AI clouds, that is the end state worth aiming for: a better token business built on a faster model.
Ready to turn Blackwell capacity into a higher-margin token service? Talk with Rafay and Minima about deploying the validated Qwen3.6-27B reference stack.
About the partners
Rafay Systems. Rafay provides the operational and economic control plane for modern AI infrastructure. Rafay Token Factory enables enterprises, neoclouds, telecommunications providers, and sovereign AI operators to publish models as governed, OpenAI-compatible, token-metered services with multi-tenancy, observability, pricing, and billing-ready usage data.
Minima. Minima develops compressed model formats, KV-cache technology, and a Blackwell-native inference runtime that reduce the hardware and memory required to serve open-weight models. Its Qwen stack combines NVFP4 W4A4 execution, model-specific kernels, and staged KV compression behind an OpenAI-compatible interface.
Methodology and references
Benchmark scope: text-generation path only; vision encoder excluded; tensor parallelism 1. Throughput is aggregate completion-token throughput. Compression ratios are versus BF16, and the staged-KV result reflects the observed page-age mix in the long-context test. Quality parity means no statistically or practically material regression under the stated non-inferiority gate; it does not mean bit-identical arithmetic.
Rafay AI Token Factory: OpenAI-compatible endpoints, multi-tenancy, token metering, pricing, quotas, and billing-ready usage data
The AI Infrastructure Race Is Shifting from GPU Capacity to Operational Execution
Rafay CEO Haseeb Budhani joins theCUBE to discuss sovereign AI, multi-tenant cloud platforms, GPU monetization, and the shift from infrastructure to AI services.
Running Sensitive Workloads on Rafay Token Factory with Protopia AI's Inference Privacy Layer
Rafay and Protopia AI eliminate plaintext exposure, letting regulated enterprises finally run sensitive workloads on shared GPU inference infrastructure.