Key takeaways
- LLM inference is the ongoing cost of running a model in production, unlike training, which happens once or periodically.
- Inference runs in two phases with different bottlenecks. Prefill is compute-bound and decode is memory-bandwidth-bound, so each responds to different optimizations.
- Quantization, distillation, KV caching, continuous batching, and speculative decoding each trade memory, compute, or quality for speed and cost, and need validation per workload.
- Measure time to first token, end-to-end latency, throughput, and inter-token latency together, alongside GPU utilization, rather than optimizing one number.
- Rafay provides the operating layer to provision, govern, and meter GPU infrastructure, so inference optimizations scale across teams and environments.
LLM inference is becoming a critical part of the AI infrastructure stack as organizations move from experimenting with models to running them in production. At scale, inference can place significant demands on GPU resources, making performance, efficiency, and infrastructure utilization increasingly important.
This article explores how LLM inference works, the techniques used to optimize it, and the infrastructure considerations that determine how efficiently AI workloads can run in production.
What Is LLM Inference?
LLM inference is the process of using a trained large language model to generate an output from a new input. When a user submits a prompt, the model processes the input as tokens and generates a response, such as text, code, a summary, or a classification. Unlike training, which builds the model, inference is the ongoing process of running that model to serve requests in production.
As organizations move AI models from experimentation into production, inference workloads can place significant demands on GPU capacity, performance, and cost. Optimizing how those workloads run is therefore critical to delivering AI applications efficiently and at scale.
Why Efficient LLM Inference Is a Business Imperative
Turning AI Investment Into Production Value
Every dollar spent training a large language model is a sunk cost until inference starts generating value. Training happens once or periodically. Inference happens continuously for as long as the model is in production, often serving millions of requests over its lifetime. That difference should shape how enterprise teams allocate engineering effort and infrastructure budgets.
The Cost of Running Inference at Scale
LLM inference is the process of feeding new inputs into a trained model and generating useful outputs, such as a summary, code completion, customer service response, or classification decision. It's where generative AI meets the real world, and the economics can become significant. A large language model serving thousands of concurrent users can consume substantial GPU resources, while high response latency can affect user experience and throughput bottlenecks can force teams to either overprovision capacity or underserve demand.
Balancing Performance, Throughput, and Cost
The business case is straightforward. Faster inference can improve user experience. Higher throughput means more requests served per GPU-hour, which can improve the return on infrastructure investment. Lower latency makes generative AI applications more responsive, while greater cost efficiency can help AI initiatives scale without infrastructure costs increasing at the same rate as adoption.
Making GPU Infrastructure Productive
Most organizations we work with have already invested heavily in GPU infrastructure. The question isn't whether to run LLM inference. It's whether that infrastructure can be used efficiently enough to justify the investment.
Efficient inference is therefore not only a model optimization problem. It is also an infrastructure operating-model problem. As workloads scale across teams, models, GPUs, and environments, organizations need visibility into capacity and consumption, along with the ability to provision resources, enforce policies, and improve utilization.
The Mechanics of Inference: Transformers, Tokens, and Phases
Understanding how inference works is essential to making informed optimization decisions. The way an LLM processes tokens and generates responses directly affects compute, memory, latency, and GPU utilization. Let's walk through the pipeline.
Tokenization
Before a large language model processes text, the input is broken into tokens. Tokens aren't necessarily words. They are subword units determined by the model's vocabulary. For example, a word such as "unbelievable" may be represented by multiple tokens. The number of input tokens affects compute and memory requirements during inference, particularly during the attention operations performed on the input sequence. As context length increases, the computational and memory demands of attention can increase significantly.
The Transformer Architecture at Inference Time
Modern LLMs are almost predominantly built on the Transformer architecture, specifically the decoder-only variant (GPT-style). Three components matter most during inference:
Self-Attention
Self-attention is the mechanism that lets each token attend to every other token in the sequence. It's what gives the model context awareness, and it's also the most computationally expensive operation. During inference, each new token generated must attend to all previous tokens, which is why generation gets slower as sequences get longer.
Positional Encodings
Positional encodings give the model a sense of token order, since Transformers have no inherent notion of sequence. Without them, "the dog bit the man" and "the man bit the dog" would be indistinguishable.
Feed-Forward Networks
Feed-forward networks in each layer apply learned transformations to each token's representation. These are compute-heavy but parallelizable, and they constitute the bulk of the model's parameters.
Two Phases: Prefill and Decode
This is where things get operationally interesting. LLM inference happens in two distinct phases, and they have very different performance profiles.
The prefill phase processes the entire input prompt in parallel. The input tokens are processed in parallel, producing the information required to begin generation and populate the growing cache. This phase is compute-bound: you're doing a lot of matrix multiplications in parallel, and GPU compute cores are well-utilized.
The decode phase is autoregressive. The model generates one token at a time, feeding each new token back as input to produce the next. This phase is memory-bandwidth-bound: each step requires reading the model's weights and the growing cache from GPU memory, but the actual computation per step is small relative to the data movement. The GPU's compute cores often sit partially idle, waiting for data.
This distinction matters because the prefill and decode phases respond to different optimizations. Throwing more compute at a memory-bandwidth problem won't help. Understanding which phase is your bottleneck shapes every optimization decision downstream, from model and runtime configuration to hardware selection and workload placement.
Model-Level Optimizations: Making Models Smaller and Faster
These techniques modify the model itself before serving, reducing its resource footprint and potentially improving inference efficiency.
Quantization
Quantization reduces the numerical precision of model weights (and sometimes activations) from higher-precision formats like FP32 or FP16 to lower-precision formats like INT8 or INT4. A model quantized from FP16 to INT8 uses roughly half the memory and can run inference faster because lower-precision arithmetic requires less memory bandwidth and compute.
The tradeoff is potential degradation in model quality. Naive quantization can hurt model quality noticeably. Modern approaches like GPTQ and AWQ use calibration data to minimize this impact, and in practice, INT8 quantization can preserve model quality sufficiently for some production workloads, but the impact needs to be validated against the specific model and use case.
INT4 is more aggressive and requires more careful validation. We've seen teams deploy INT4 models successfully for latency-sensitive applications where slight quality reductions are acceptable, but you need to benchmark against your specific use case.
The practical benefit can be significant: if quantization allows a model to run on two GPUs instead of four, it can substantially reduce the infrastructure required to serve that workload.
Model Distillation
Distillation trains a smaller "student" model to mimic the behavior of a larger "teacher" model. The student learns not just the correct answers but the teacher's probability distributions across all possible tokens, capturing more subtle knowledge than training on raw data alone.
The result is a smaller model that performs closer to the large model's quality than its parameter count would suggest. Distillation requires its own training run, so it's an upfront investment. For high-volume inference workloads serving large numbers of similar requests, the resulting reduction in model size and compute requirements can produce substantial ongoing savings.
Pruning
Pruning removes redundant or low-impact weights and structures from the model. Structured pruning, such as removing entire attention heads or layers, is generally more practical for inference speedups than unstructured pruning because modern GPU hardware is optimized for dense operations. The pruned model can be smaller and faster, but quality validation remains essential.
Runtime Optimizations: Techniques for Efficient Serving
These techniques primarily change how inference is executed rather than changing the model itself. Some architectural choices, such as MQA and GQA, can also influence how efficiently a model is served.
KV Caching
During the decode phase, each new token needs to use the attention information from the preceding context. Without caching, this would require repeatedly recomputing key and value vectors for previous tokens at each generation step. KV caching stores these intermediate results so they do not need to be recalculated.
This is a straightforward memory-for-compute tradeoff. KV caching can dramatically reduce redundant computation during the decode phase, but the cache itself consumes GPU memory and grows with sequence length and batch size. For long-context workloads, KV cache memory can become a significant portion of total GPU memory consumption and, in some configurations, can exceed the memory required for model weights. Managing KV cache memory efficiently is therefore an important challenge in production inference serving.
Batching
Processing multiple requests simultaneously can improve GPU utilization. Static batching waits until a fixed number of requests arrive, then processes them together. This is simple but can be inefficient; if requests have different sequence lengths, shorter requests may sit idle while longer requests complete.
Continuous batching, also called iteration-level batching, is more sophisticated. As soon as one request in a batch finishes generating, a new request can take its slot without waiting for the entire batch to complete. This keeps the GPU occupied more consistently and is supported by many modern serving frameworks.
Attention Architectures That Affect Inference Efficiency
Standard Multi-Head Attention (MHA) maintains separate key, value, and query projections for each attention head. MQA shares a single set of key and value projections across all heads, reducing KV cache size and memory bandwidth requirements. Grouped-Query Attention (GQA) is a middle ground, sharing key-value projections across groups of heads rather than all of them.
These aren't runtime settings you apply to an existing model. They are architectural choices made during model development and training. However, when choosing between models for deployment, attention architecture can influence serving efficiency. GQA can reduce KV cache requirements and memory bandwidth demands compared with MHA, which can improve serving efficiency depending on the model, workload, and hardware.
Speculative Decoding
Speculative decoding uses a small, fast "draft" model to generate several candidate tokens, which the larger target model then verifies in a single forward pass. When the draft model's predictions are accepted at a high enough rate, the approach can increase generation speed while retaining the target model's output quality.
The tradeoff is that you're running two models, which adds complexity and memory overhead. It works best when the draft model is significantly faster, and its predictions align with the target model often enough to justify the additional overhead.
Measuring What Matters: Key Inference Performance Metrics
Without clear metrics, optimization is guesswork. The right metrics help teams understand how inference workloads perform, how efficiently GPU capacity is being used, and where optimization efforts can have the greatest impact.
Time to First Token (TTFT)
Time to First Token (TTFT) measures the delay between receiving a request and generating the first output token. It is influenced heavily by the prefill phase and is an important measure of responsiveness for interactive applications.
For applications where users interact with a model in real time, reducing TTFT can make responses feel more responsive. The appropriate target depends on the application and user experience requirements.
End-to-End Latency
End-to-end latency captures the total time from receiving a request to completing the response. This includes both prefill and the full decode sequence.
For streaming applications, TTFT and inter-token latency may be more important to perceived responsiveness because users see tokens appearing progressively. For batch or API-driven workloads, end-to-end latency may be a more important measure of overall performance.
Throughput
Throughput can be measured as tokens per second across all requests or requests per second. It provides an important view of how much inference work the serving infrastructure can process over a given period.
Higher throughput at an acceptable latency can improve GPU utilization and reduce the infrastructure cost associated with each inference request. However, throughput should always be evaluated alongside latency and workload requirements rather than optimized in isolation.
Inter-Token Latency
Inter-token latency, also called time per output token (TPOT), measures the delay between consecutive tokens during the decode phase. This affects the perceived "typing speed" of streaming responses and can be an important metric for interactive applications.
Balancing the Metrics
These metrics interact. Increasing batch size can improve throughput and GPU utilization while also increasing TTFT and per-request latency. The right balance depends on your service-level requirements and workload characteristics.
Set targets for each metric based on the application's requirements, then optimize against those targets rather than chasing a single performance number. Looking at these metrics alongside GPU utilization and resource consumption provides a more complete picture of inference efficiency.
Choosing Your Toolkit: A Look at Popular Inference Frameworks
The inference serving framework you choose determines which optimizations are available and how much engineering effort integration requires. Different frameworks are optimized for different models, hardware environments, and workloads, so the right choice depends on the requirements of your deployment.
vLLM
vLLM has gained significant adoption for its implementation of PagedAttention, which manages KV cache memory in a way that helps reduce memory fragmentation and improve serving efficiency. It supports continuous batching, integrates with Hugging Face models, and is open source, making it a widely used option for teams deploying LLM serving workloads.
TensorRT-LLM
TensorRT-LLM is NVIDIA's optimized inference library, purpose-built for NVIDIA GPUs. It applies techniques such as kernel fusion, quantization, and tensor parallelism to optimize LLM inference on NVIDIA hardware. Because it is designed specifically for NVIDIA GPUs, its benefits are closely tied to NVIDIA's hardware and software ecosystem, and integration can require more specialized engineering.
DeepSpeed-Inference
DeepSpeed-Inference from Microsoft extends the DeepSpeed training library with inference-specific optimizations, including tensor parallelism for multi-GPU serving and optimized kernels. It can be a natural choice for teams already using DeepSpeed for training.
Key considerations when choosing:
- Which models do you need to serve?
- What hardware are you deploying on?
- How important is ease of deployment versus raw performance?
- Do you need multi-GPU or multi-node support?
No single framework wins on every axis. In practice, many organizations run different frameworks for different workloads, which creates its own management complexity.
The Critical Role of Hardware and Infrastructure Orchestration
Software optimizations can improve inference efficiency, but they still depend on the hardware and infrastructure running the workload. GPU memory, memory bandwidth, capacity, and workload placement all influence how efficiently inference can run at scale.
Hardware performance per GPU is only part of the picture. Distributed infrastructure across on-premises environments, cloud regions, and multiple providers can create visibility gaps, leading to underutilized capacity and overprovisioning. Teams need to understand where GPU capacity is available, how it is being consumed, and how workloads can be scheduled efficiently.
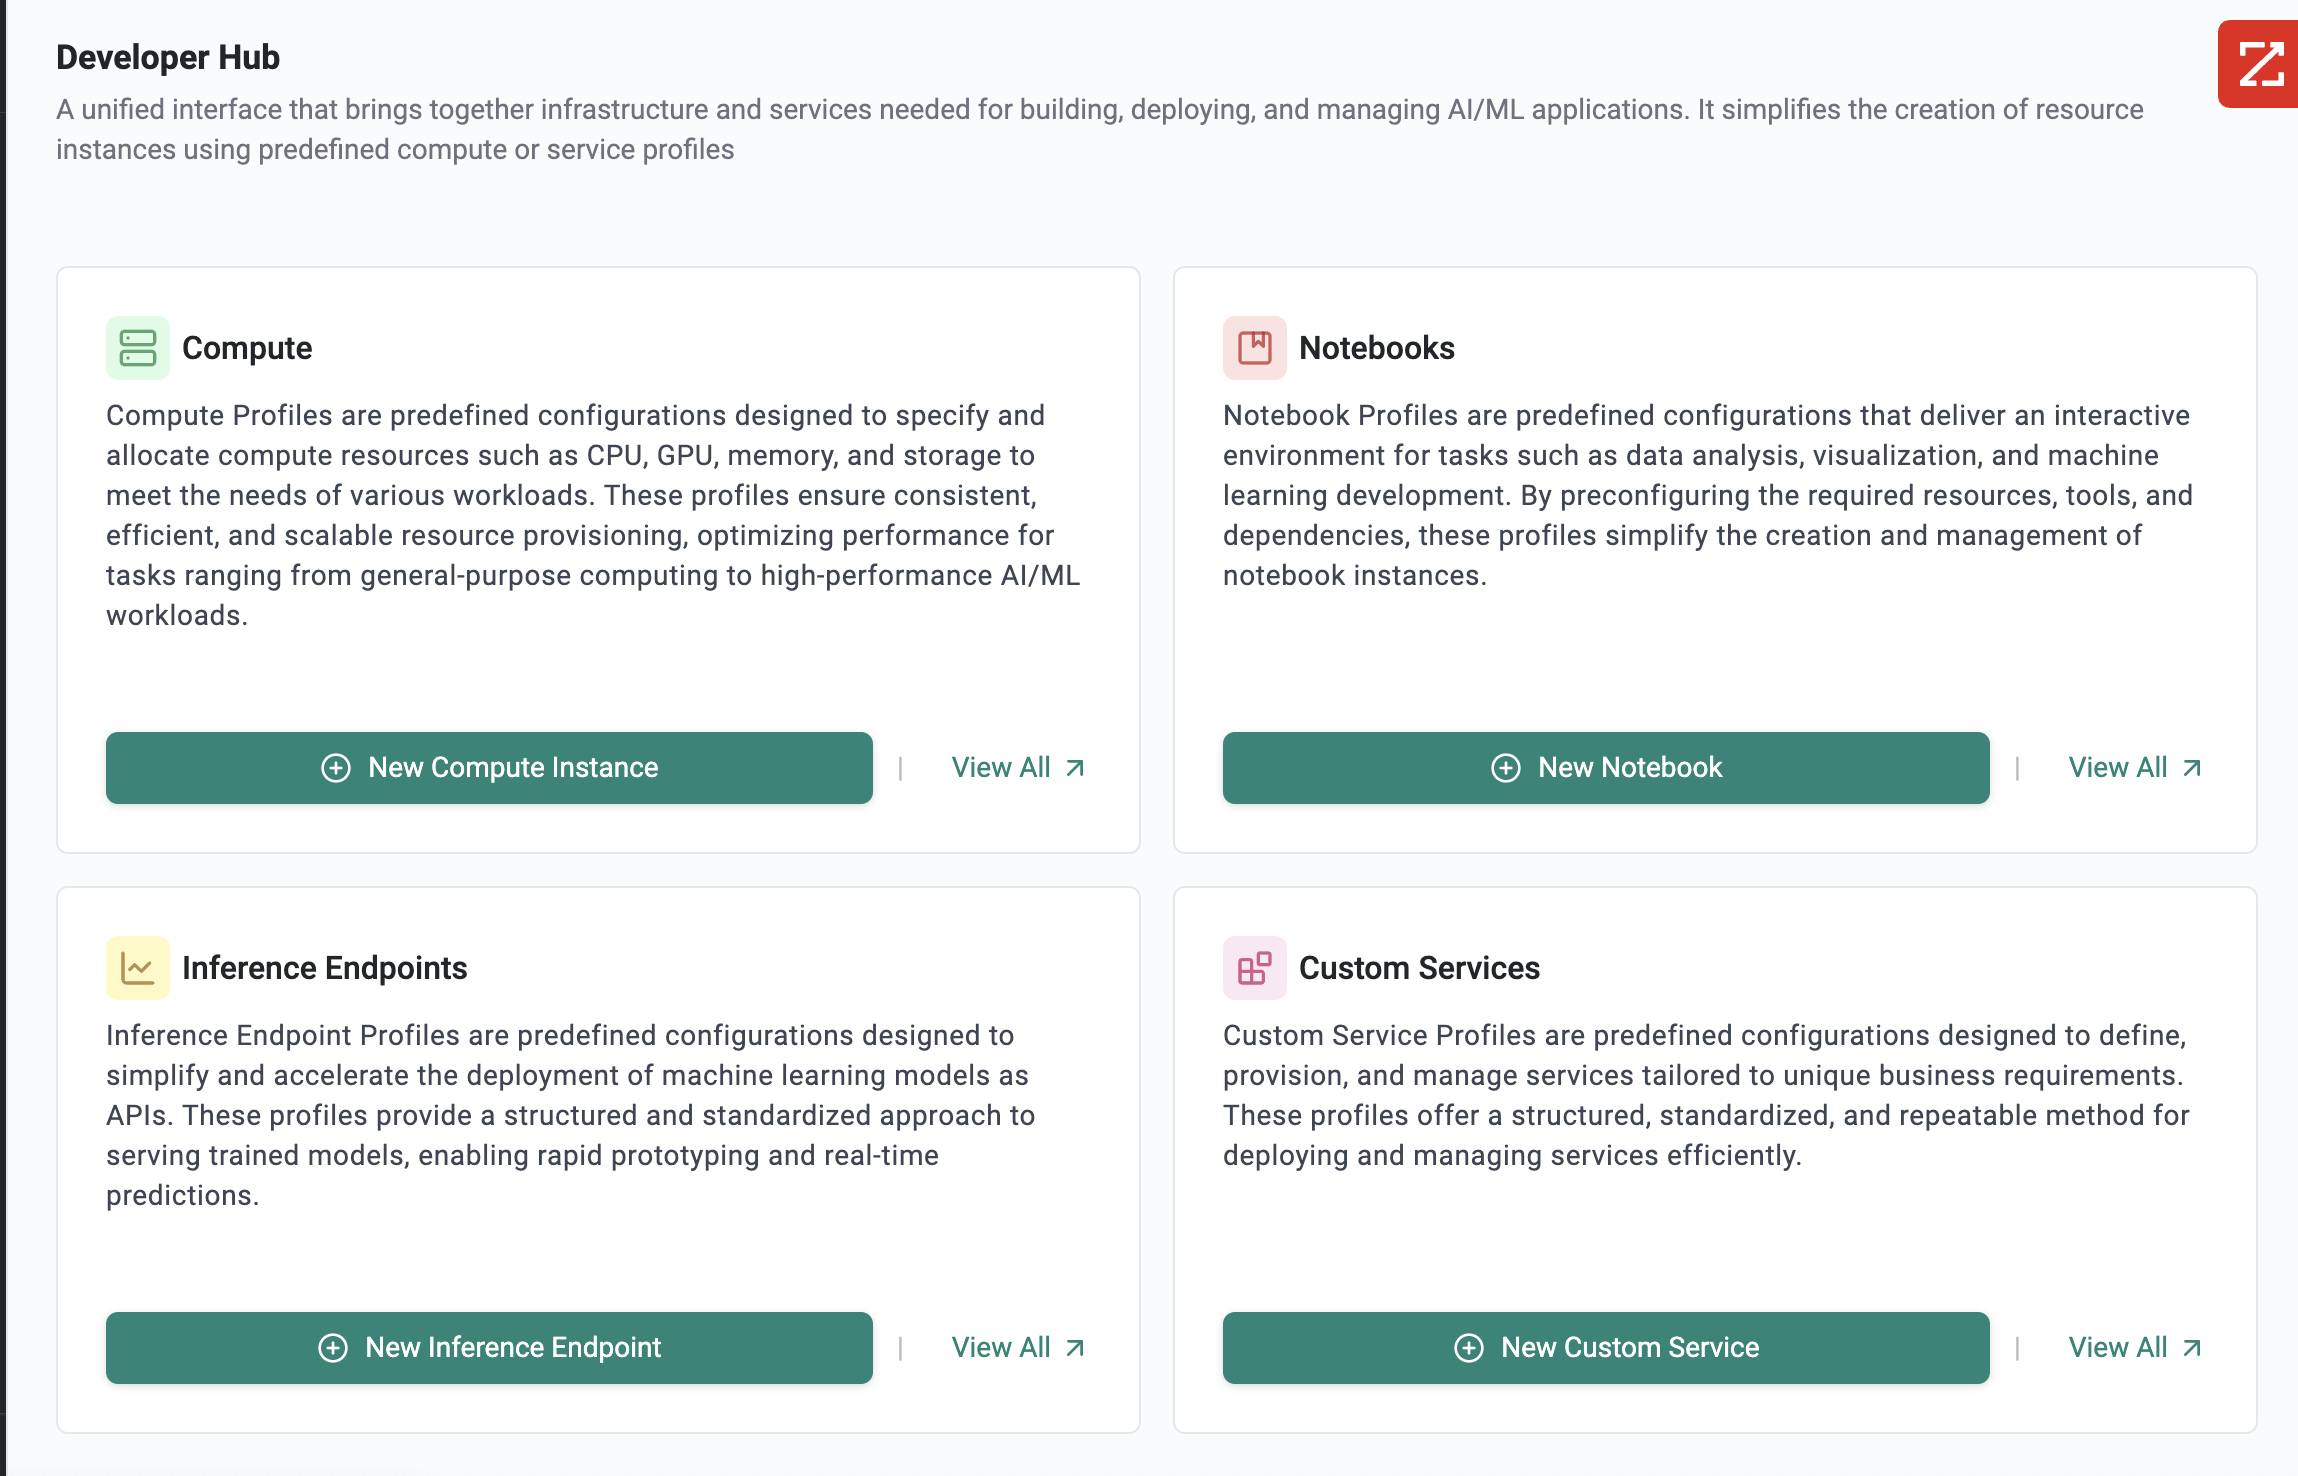
Rafay provides the infrastructure operating layer for managing distributed GPU and CPU environments across hybrid and multi-cloud deployments. With capabilities such as automated provisioning, multi-tenant governance, policy enforcement, usage metering, and workload orchestration, Rafay helps platform teams make GPU infrastructure more accessible, measurable, and efficient for AI workloads.
Building Your AI Factory With Rafay: Next Steps in Inference Mastery
LLM inference optimization spans the model, runtime, frameworks, hardware, and infrastructure. The challenge is turning those individual optimizations into an operating model that can scale across workloads while maintaining performance, utilization, governance, and cost control.
Rafay provides the infrastructure operating layer to help organizations turn GPU infrastructure into self-service, governed, and measurable AI services. With automated provisioning, multi-tenant governance, usage visibility, and infrastructure orchestration, Rafay helps platform teams make AI infrastructure easier to consume, manage, and scale.
Frequently Asked Questions
Why is efficient LLM inference important for businesses?
Efficient LLM inference is important because inference is an ongoing cost once a model is deployed. Improving latency, throughput, and GPU utilization can improve the efficiency of production workloads and help organizations get more value from their AI infrastructure investment.
What are the two main phases of LLM inference, and how do they differ?
LLM inference occurs in two main phases: prefill and decode. The prefill phase processes the input prompt and is generally compute-bound, while the decode phase generates output tokens sequentially and is more heavily influenced by memory bandwidth and KV cache requirements.
How does quantization improve LLM inference performance and reduce cost?
Quantization reduces the numerical precision of model weights, typically from formats such as FP16 to INT8 or INT4. This can reduce memory requirements and improve inference efficiency, potentially allowing models to run on fewer or smaller GPUs. The impact on model quality should be validated for the specific workload.
What is continuous batching, and how does it increase LLM inference throughput?
Continuous batching, also known as iteration-level batching, allows new requests to enter a batch as existing requests complete. This can keep GPUs more consistently utilized and improve throughput compared with static batching, although the impact on latency depends on the workload.
What are the most important metrics to track for LLM inference performance?
Key metrics include Time to First Token (TTFT), end-to-end latency, throughput, and inter-token latency. GPU utilization and resource consumption provide additional insight into how efficiently the underlying infrastructure is being used.
How does GPU memory bandwidth impact LLM decode performance?
GPU memory bandwidth affects LLM decode performance because each generation step requires access to model weights and KV cache data. Higher memory bandwidth can improve data movement during generation, although overall performance also depends on the model, workload, and serving configuration.
What are common challenges when monitoring GPU utilization across hybrid cloud environments?
Hybrid environments can make GPU utilization difficult to track because capacity may be distributed across on-premises infrastructure, cloud regions, and multiple providers. Limited visibility can contribute to underutilization and overprovisioning, making it harder to schedule workloads efficiently and manage infrastructure costs.
How does Rafay help operationalize LLM inference?
Rafay provides the infrastructure operating layer for running AI workloads at scale, helping organizations manage GPU infrastructure with self-service access, multi-tenant governance, policy enforcement, usage visibility, and automated provisioning. This helps teams move from optimizing individual inference workloads to operating AI services consistently across distributed infrastructure.