The AI infrastructure market is moving beyond raw GPU capacity. The durable opportunity lies in turning that capacity into governed, consumable AI services that multiple customers and internal teams can use safely and concurrently. Delivering those services requires two coordinated layers: infrastructure provisioning and governance, and workload scheduling and GPU allocation.
Rafay, an NVIDIA DSX ecosystem partner, is a launch partner for today’s release of NVIDIA Run:ai as an open-source platform. NVIDIA Run:ai provides AI workload and GPU orchestration within NVIDIA DSX OS, the open, modular software portfolio of the NVIDIA DSX AI Factory Platform. It schedules workloads and allocates shared GPU capacity across teams and projects, maximizing utilization and workload throughput.
Building on its existing NVIDIA Run:ai integration, Rafay delivers the open-source platform through a governed, self-service experience. Rafay automates deployment and lifecycle management across the Kubernetes infrastructure and NVIDIA Run:ai environment, enabling operators to publish NVIDIA Run:ai as a self-service SKU in their service catalogs. Customers and internal teams can select a predefined configuration and provision the complete environment on demand. Together, Rafay and NVIDIA Run:ai enable operators to offer governed, on-demand AI services while maintaining consistent control from the underlying Kubernetes infrastructure through workload scheduling and GPU allocation.
Why scheduling decides the economics
A GPU fleet only earns when workloads are actually running on it. The scheduler is the layer that decides which jobs run where, how GPUs are shared across teams and tenants, and how quickly compute is freed and reassigned as demand shifts.
NVIDIA Run:ai open-source software brings scheduling capabilities that operators would otherwise have to build and maintain themselves. Fair-share scheduling balances access across many tenants. Gang scheduling supports distributed training. Dynamic quotas adjust to real demand rather than static allocations. The result is more useful work from the same fleet and a better experience for the developers and customers consuming it.
How Rafay extends NVIDIA Run:ai
Rafay is the infrastructure orchestration and control plane. It turns bare-metal, virtualized, and Kubernetes environments into secure, multi-tenant, self-service platforms with governance, quotas, and policy built in. NVIDIA Run:ai open-source software is the GPU scheduling and workload orchestration layer that runs on top.
Rafay transforms Run:ai from a manually deployed application into a consumption-ready product that a GPU cloud, enterprise, or sovereign operator can offer with confidence. Operators do not build or maintain the integration themselves. They publish a SKU, and their customers consume NVIDIA Run:ai on demand.
What the integration looks like on the Rafay platform
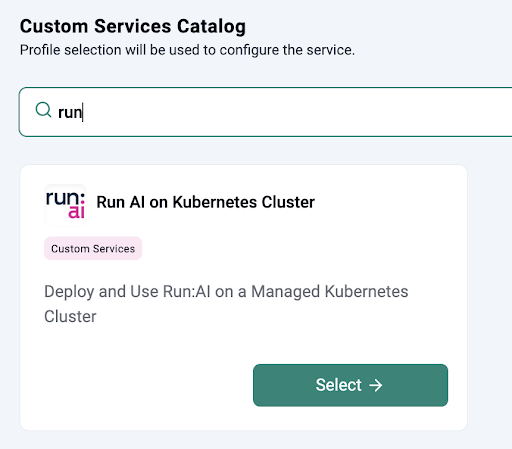
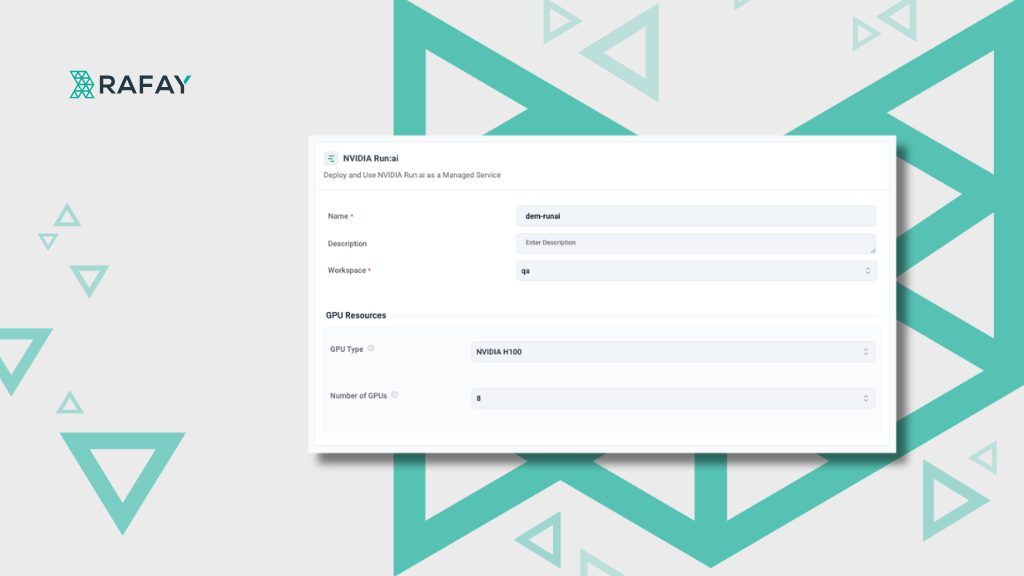
The experience begins in the operator's marketplace or self-service portal. A customer selects a Run:ai SKU, and Rafay orchestrates everything behind that single selection. It provisions the GPU infrastructure, stands up a managed Kubernetes cluster, installs the required operators, and creates a ready-to-use Run:ai tenant. The customer is working in Run:ai after automated provisioning, without requiring a manual integration.
[Self-service catalog. The "Run AI on Kubernetes Cluster" card in the operator's Custom Services Catalog]
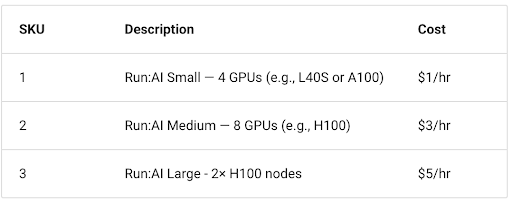
Operators define the SKUs. Each SKU maps to a pre-set configuration of GPU type and count, so a provider can publish tiers that match different customer needs and price points. An illustrative set from the Rafay documentation:
SKU tiers. The SKU table showing Small / Medium / Large variants by GPU type and count
Pricing for each tier is set by the provider (the documentation uses illustrative figures such as $1, $3, and $5 per hour). Behind every SKU, Rafay handles the full lifecycle: provisioning, multi-tenancy, governance, and cluster onboarding. The complexity of deploying Run:ai and its infrastructure is hidden behind one selection, which is what turns Run:ai from a complex integration into a repeatable, monetizable service.
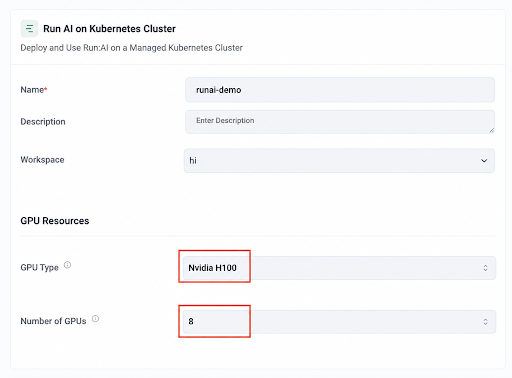
One-click configuration. The "Run AI on Kubernetes Cluster" form showing pre-set fields such as GPU Type and Number of GPUs
The operator opportunity
Neoclouds and GPU cloud providers get a faster path to a differentiated, self-service AI cloud. Predictable, standardized SKUs let them onboard dozens or hundreds of tenants without custom engineering per customer, and capture margin by packaging a governed AI service on top of their compute.
Enterprises get governed, multi-tenant GPU access for AI and ML teams, with scheduling that keeps expensive compute working and policy controls that support governance requirements, delivered as a self-service catalog item rather than a ticket queue.
Sovereign AI clouds get a governed platform that serves many tenants at national scale, with data residency and scheduling control retained by the operator.
Across all three, the pattern is the same. Rafay handles provisioning, tenancy, and governance and packages the result as a SKU. NVIDIA Run:ai open-source software handles scheduling. Together they turn GPU capacity into a consumable AI platform.
Availability and technical readiness
The one-click Run:ai deployment is available on the Rafay platform today and documented in Rafay's product documentation. Operators can publish Run:ai as a self-service SKU that provisions GPU infrastructure, a Kubernetes cluster, the required operators, and a Run:ai tenant automatically.
The expanded integration is aligned to the open-source release of the NVIDIA Run:ai platform. It extends today's deployment from the Run:ai scheduler to the broader set of components NVIDIA is newly open-sourcing, adds deeper integration with the Run:ai policy and scheduling engine, and packages the available open-source components as part of the core Rafay platform offering.
“With NVIDIA Run:ai now open source, every operator can put advanced GPU scheduling to work, and we’re proud to be a launch partner. Rafay packages the full stack, from GPU infrastructure through to a ready-to-use Run:ai tenant, behind a single catalog selection, so operators can publish it as a SKU and their customers can consume it on demand.”
Mohan Atreya · Co-founder and Chief Product Officer, Rafay
With NVIDIA Run:ai open-source software available to operators, the advantage moves to whoever can turn it into a governed, consumable service the fastest. That is what Rafay delivers. A neocloud, enterprise, or sovereign AI cloud can publish Run:ai as a self-service SKU and put it in their customers' hands on day one.
How GPU Clouds Deliver NVIDIA Run:ai as Self-Service with Rafay GPU PaaS
Learn how Rafay GPU PaaS enables GPU Clouds to offer NVIDIA Run:ai as a fully automated, multi-tenant managed service delivered through self-service with lifecycle management and turnkey deployment.